
Paperclip in Spree: Extending Product Image Sizes
By Steph Skardal
June 6, 2011
Spree uses the popular gem Paperclip for assigning images as attachments to products. The basic installation requires you to install the gem, create a migration to store the paperclip-specific fields in your model, add the has_attached_file information to the model with the attachment, add the ability to upload the file, and display the file in a view. In Spree, the Image model has an attached file with the following properties:
class Image < Asset
  ...
  has_attached_file :attachment,
                    :styles => { :mini => '48x48>',
                      :small => '100x100>',
                      :product => '240x240>',
                      :large => '600x600>'
                    },
                    :default_style => :product,
                    :url => "/assets/products/:id/:style/:basename.:extension",
                    :path => ":rails_root/public/assets/products/:id/:style/:basename.:extension"
  ...
end
As you can see, when an admin uploads an image, four image sizes are created: large, product, small, and mini.
Four images are created per product image uploaded in Spree …
ecommerce graphics spree
Saving time with generate_series()
By Josh Tolley
May 31, 2011
I was giving a presentation once on various SQL constructs, and, borrowing an analogy I’d seen elsewhere, described PostgreSQL’s generate_series() function as something you might use in places where, in some other language, you’d use a FOR loop. One attendee asked, “So, why would you ever want a FOR loop in a SQL query?” A fair question, and one that I answered using examples later in the presentation. Another such example showed up recently on a client’s system where the ORM was trying to be helpful, and chose a really bad query to do it.
The application in question was trying to display a list of records, and allow the user to search through them, modify them, filter them, etc. Since the ORM knew users might filter on a date-based field, it wanted to present a list of years containing valid records. So it did this:
SELECT DISTINCT DATE_TRUNC('year', some_date_field) FROM some_table;In fairness to the ORM, this query wouldn’t be so bad if some_table only had a few hundred or thousand rows. But in our case it has several tens of millions. This query results in a sequential scan of each of those records, in order to build a list of, as it turns out, about fifty total …
postgres sql
Postgres Bug Tracking - Help Wanted!
By Greg Sabino Mullane
May 29, 2011
Once again there is talk in the Postgres community about adopting the use of a bug tracker. The latest thread, on pgsql-hackers, was started by someone asking about the status of their patch. Or rather, asking an even better meta-question about how one finds out the status of a PostgreSQL bug report or patch. Sadly, the answer is that there is no standard way, other than sending emails until someone replies one way or another. The current process works something like this:
- Someone finds a bug1. They send an email to pgsql-bugs@postgresql.org OR they use the web form, which grabs a sequential number and mails the report to pgsql-bugs@postgresql.org. Nothing else is done/stored, it just sends the email.1. Someone replies about the bug OR nobody replies about the bug.1. After a fix is found, which may involve some emails on other mailing lists, someone replies that the bug is fixed on the original thread. Maybe.
As you can see, there is some room for improvement there. Some of the most major and glaring holes in the current system:
- No way to search previous / existing bugs
- No way to tell the status of a bug
- No way to categorize and group bugs (per version, per platform, per …
community database open-source postgres
End Point to be at Internet Retailer 2011
By Steph Skardal
May 27, 2011
We’re excited to announce that End Point will be in full force at Internet Retailer 2011. A team of six (Rick, Ben, Jon, Ron, Carl, and myself) will be managing a booth during the 3 day Conference and Exhibition in San Diego from June 14th-17th.
We’re hoping to reach out to future clients to discuss our services including ecommerce develpoment and support, database development and support, systems architecture, hosting, and Liquid Galaxy build, maintenance and support. We’ll also have a Liquid Galaxy display to show off as part of our exhibit. We have a couple of conference passes so hopefully we’ll attend a few sessions and share some details about those sessions here on our blog!
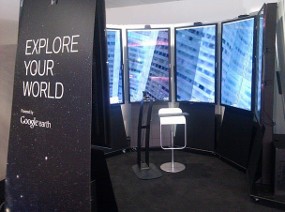
Please come by our booth at the conference to meet us or to say hi! We’re excited to talk to you about what we can do to help your business succeed.
company conference ecommerce visionport
Spree Performance Benchmarking
By Steph Skardal
May 25, 2011
I see a lot of questions regarding Spree performance in the spree-user group, but they are rarely answered with metrics. I put together a quick script using the generic benchmark tool ab to review some data. Obviously, the answer to how well a site performs and scales is highly dependent on the host and the consumption of the web application, so the data here needs to be taken with a grain of salt. Another thing to note is that only two of the following use cases are running on Rails 3.0 — many of our current Spree clients are on Spree 0.11.2 or older. I also included one non-Spree Rails ecommerce application, in addition to a few non-Rails applications for comparison. All of the tests were run from my home network, so in theory there shouldn’t be bias on performance tests for sites running on End Point servers.
| ab -n 100 | |||||
| -c 2 homepage | -c 20 homepage | -c 2 product page | -c 20 product page | ||
| Client #1 Spree: 0.11.2 Hosting: 4 cores, 512 GB RAM DB: MySQL # Products: <100 | 7.49 | 24.75 | 6.49 | 19.87 | Requests per second |
| 266.889 | 808.041 | 307.997 | 1006.552 | Time per request (ms) | |
| Client #2 Spree 0.11.2 Hosting: Engineyard, medium instance DB: MySQL … | |||||
interchange performance rails scalability spree magento
Raising open file descriptor limits for Dovecot and nginx
By Jon Jensen
May 23, 2011
Recently we’ve needed to increase some limits in two excellent open-source servers: Dovecot, for IMAP and POP email service, and nginx, for HTTP/HTTPS web service. These are running on different servers, both using Red Hat Enterprise Linux 5.
First, let’s look at Dovecot. We have a somewhat busy mail server and as it grew busier, it occasionally hit connection limits when the server itself still has plenty of available capacity.
Raising the number of processes in Dovecot is easy. Edit /etc/dovecot.conf and change from the prior (now commented-out) limits to the new limits:
#login_max_processes_count = 128
login_max_processes_count = 512
and later in the file:
#max_mail_processes = 512
max_mail_processes = 2048
However, then Dovecot won’t start at all due to a shortage of available file descriptors. There are various ways to change that, including munging the init scripts, changing the system defaults, etc. The most standard and non-interventive way to do so with this RHEL 5 Dovecot RPM package is to edit /etc/sysconfig/dovecot and add:
ulimit -n 131072That sets the shell’s maximum number of open file descriptors allowed in the init script /etc/init.d/dovecot before the Dovecot …
hosting redhat
Coding Tips from RailsConf 2011
By Steph Skardal
May 20, 2011
A couple of the sessions I attended on Day 1 of RailsConf 2011 were along the lines of how to write good Rails code: Keeping Rails on the Tracks by Mikel Lindsaar and Confident Code by Avdi Grimm. Here’s a mishmash summary from these talks. Although the talks didn’t focus on Ruby and Rails techniques, both talks had plenty of examples and tips for writing maintainable code that apply to my world of consulting and development.
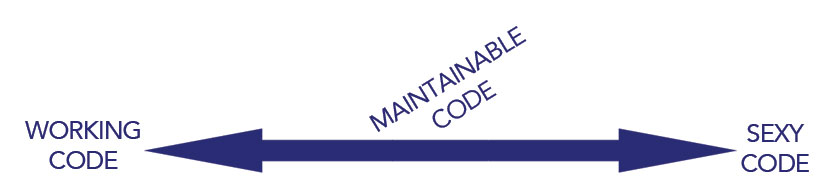
In the first talk, Mikel talked about what he meant by keeping Rails on the Tracks and the balance that we might often experience between just working code and sexy code. Maintainable code lands in the middle there somewhere. And he briefly touched on the fact that budget matters in writing maintainable code, trade-offs are part of life, and that you are selling a solution and not code, which means that clients don’t really care about the technology as long as it’s maintainable.
Mikel’s first pro tip for building a maintainable Rails app is to treat deployment as a first class citizen by having trivial deployment that takes advantage of existing tools like Chef and Puppet. Using Bundler will help you avoid additional pain, but be careful of avoiding locking …
conference rails
JavaScript and APIs at RailsConf 2011
By Steph Skardal
May 19, 2011
A big trend of RailsConf 2011 has been the presence of JavaScript, whether it be talk of CoffeeScript, node.js, Sproutcore, backbone.js, etc. I attended Yehuda Katz’s talk on Building Rails Apps for the Rich Client on Day 4 of the conference.
Part 1: Rails versus Sinatra Smackdown
Yehuda gave a two part talk about developing API-heavy applications. The first bit addressed why to develop in Rails rather than Sinatra if your application is API-heavy and doesn’t appear to be utilizing valuable parts of Rails? This is fairly applicable to a couple of Sinatra projects that I’ve done at End Point — I like Sinatra a lot, but at some point you begin to replicate parts of Rails. Yehuda explained that because it’s easy to develop web applications efficiently using Rails conventions, developers can become forgetful/ignorant of the underlying functionality of Rails that doesn’t ship with something like Sinatra, much like how working with an ORM can breed developers who aren’t familiar with the underlying database interactions. The checklist for things that Rails manages we might forget about includes:
- ActionDispatch internals
- Session deserialization
- Browser standards mode
- Cookie abstraction …
conference javascript rails